Baidu Wenxin Large Model released ERNIE-5.5-Flash-Base today, making available the weights from the 5.5 Flash pre-training endpoints of ERNIE.
This is a sparse MoE language model with a total of 280B parameters. 14B parameters are activated per token. Pre-training was completed from scratch on 33.5T of tokens; the maximum training context is 128K, and fine-tuning and inference support up to 1M tokens contexts.
The weights released this time have not undergone intermediate training or post-training, and can serve as a common starting point for domain adaptation, command fine-tuning, and reinforcement learning research.
The official stated that the Base model is just a starting point. Subsequently, the more trained ERNIE 5.5 and Flash models will be launched.
ERNIE-5.5-Flash-Base completes pre-training from scratch on 33.5T tokens, using an Muon optimizer and FP8 mixed precision. The pre-training corpus covers a wide range of domains and languages, with a focus on building in three key directions:
- Web page data: multi-language web page crawling, high-fidelity text extraction, and model-driven multi-dimensional quality filtering.
- Code data: Repository and web page code undergo non-code filtering, deduplication, and quality grading, and are supplemented with commit, issue, pull, request, code review, automatically generated tests, and repair data verified by CI as part of software evolution and execution verification processes.
- Long-text data: Selected natural long documents, long sequences mixed with semantically similar search-interfering text, as well as synthesized search data, citation-based Q&A, and multi-hop Q&A data.
According to the introduction, the training system and model architecture are designed in coordination. The optimizer utilizes a distributed Muon; at a scale of several thousand cards, the inter-machine communication between the Dense parameter and the MoE parameter is combined into a single collective communication, which reduces inter-machine latency and jitter. The attention operator adopts a FlashMask-4 based on CuTe-DSL, supporting SM90 and SM100 architectures. head dim supports up to 576 (qk)/512 (v), and can be directly used for calculations with a 512-dimensional width at the HCA layer.
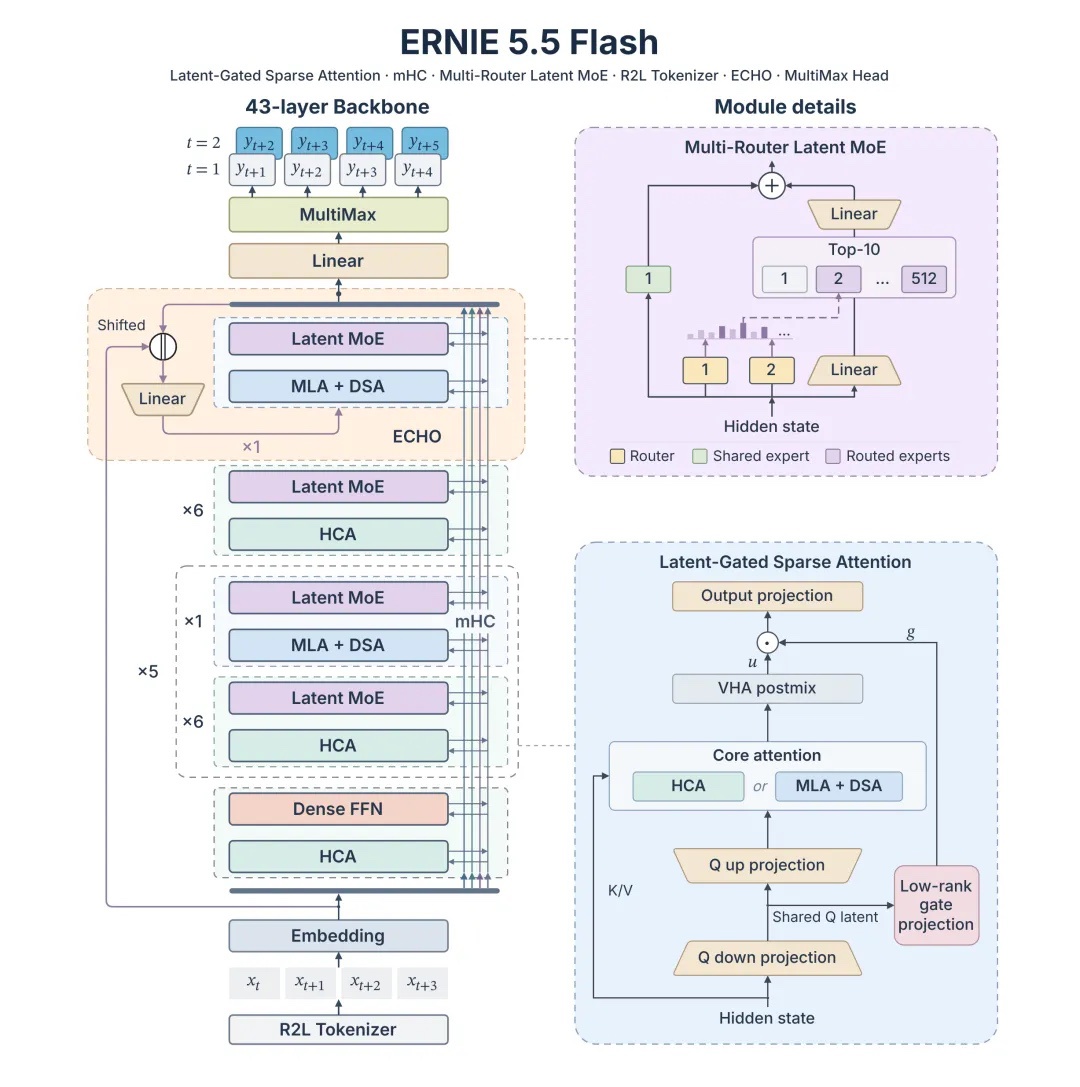
IT Home with evaluation data and open-source links:
The Wenxin Large Model was evaluated on 30 Benchmark tasks, covering seven categories of abilities: comprehensive, knowledge, science, reasoning, multilingual, coding, and long-context understanding. The results of Base models DeepSeek-V4-Flash-Base, Hy3-preview-Base, and MiMo-V2.5-Base of similar scale were also listed. All four models are based on their publicly released checkpoint and used the same evaluation framework. ERNIE-5.5-Flash-Base performed well in all ability dimensions; in terms of long-context understanding, although 37 out of 43 layers performed attention operations on sequences compressed by 128 times, just 6 layers of MLA-DSA were sufficient to support fine-grained retrieval. For the complete table, please refer to the Hugging Face model card.
Technical Blog: https :// ernie.baidu.com / zh / release / ernie-5-5-flash-base /
Hugging Face ( FP8 ) : https :// huggingface.co / baidu / ERNIE-5.5-Flash-Base
Hugging Face ( BF16 ) : https :// huggingface.co / baidu / ERNIE-5.5-Flash-Base-BF16
Tuning example ( Megatron-Bridge ) : https :// github.com / NVIDIA-NeMo / Megatron-Bridge / tree / main / examples / models / ernie55