News from the IT community on October 10th: Cloudflare announced yesterday (October 9th) the launch of an open-weight decision-making model, Clef-omni, which supports single API calls for processing text, images, audio, and video, among other things.
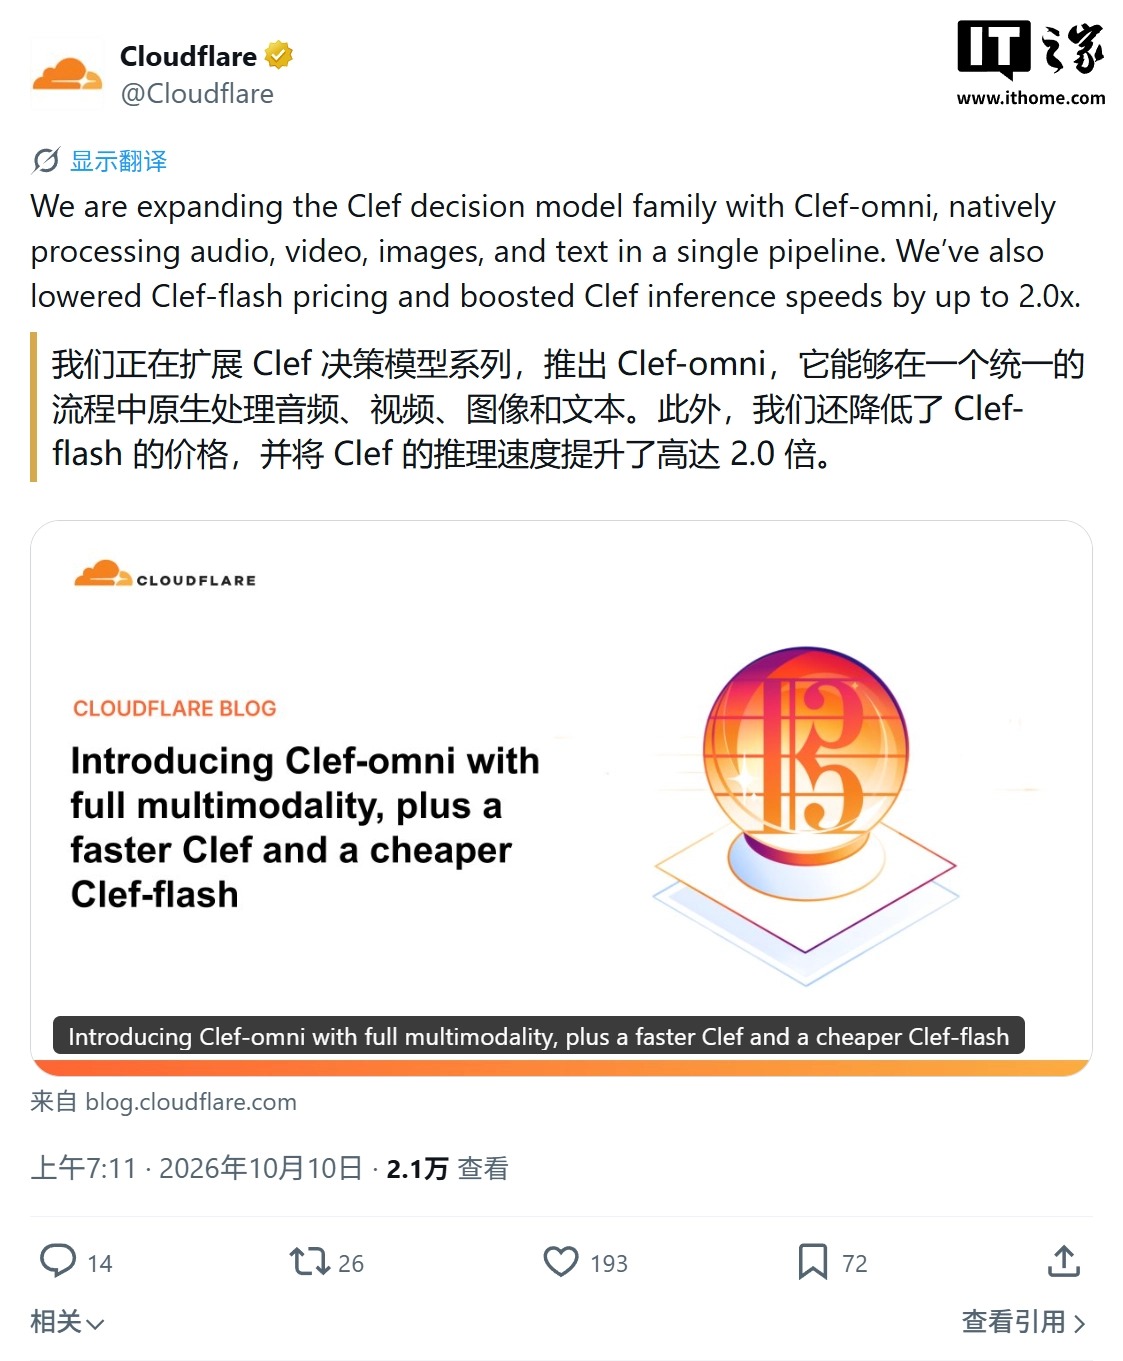
In terms of positioning, this model has expanded support for multimodal input based on the previous Clef series of models, and the model weights have been made available in Hugging Face.
In terms of multimodal support, the previous Clef supported text, images, and consecutive frames extracted from videos (extracting the video into static images over time and then feeding these images to the model in sequence). The new Clef-omni adds audio and full video inputs, while wav, mp3, mp4, and webm formats are also supported.
According to Cloudflare, developers do not need to set up separate processes for speech transcription and audio-video segmentation; they can use a single model to process multiple types of inputs.
According to Cloudflare, Clef-omni is built upon Qwen3-Omni-30B-A3B-Instruct and retains its main cognitive capabilities. This model is designed for structured decision-making tasks and does not generate conventional text outputs. In the tests published by the company, the median response time for pure text requests was about 130 milliseconds, for images it was around 150 milliseconds; for 21-second videos with sound, the scoring process was completed in about 1.5 seconds.
Cloudflare also reduced the price from Token per million inputs from $0.09 (Note from IT: the current exchange rate is approximately 0.6 RMB) to $0.038 (the current exchange rate is approximately 0.25 RMB), a decrease of about 58%. Clef-flash The context window size for the hosted version was also reduced from 64k to 24k.