On September 30th, at the 2026 OpenAI Developer Day event held on that day, OpenAI launched a brand-new Ultrafast service tier. Officials stated that this service can provide up to 8 times the token (Token) generation speed in Codex, and can achieve a maximum generation speed of 6 times when called in API.
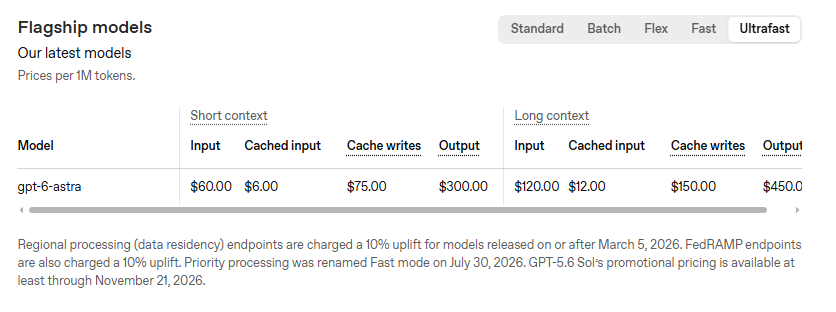
Regarding the call charges for API, after querying the official information from the IT website, the following is the description of the selling prices:
- Cache writing ( Cached input write ): The first time you save a piece of input content into the prompt cache, you usually need to pay a fee for "writing to cache".
- Caching input ( Cached input ): Subsequent requests reuse the previously saved portion of the input, which is usually charged at a lower price.
OpenAI Official announcement: GPT-6 Astra Ultrafast can achieve 300 tokens per second in Codex. Currently, this service is available for API calls, and Pro 500 subscribed users and enterprise users can experience it in ChatGPT Work and Codex. The official also stated that they will introduce GPT-6.1 Sol Ultrafast in the future.
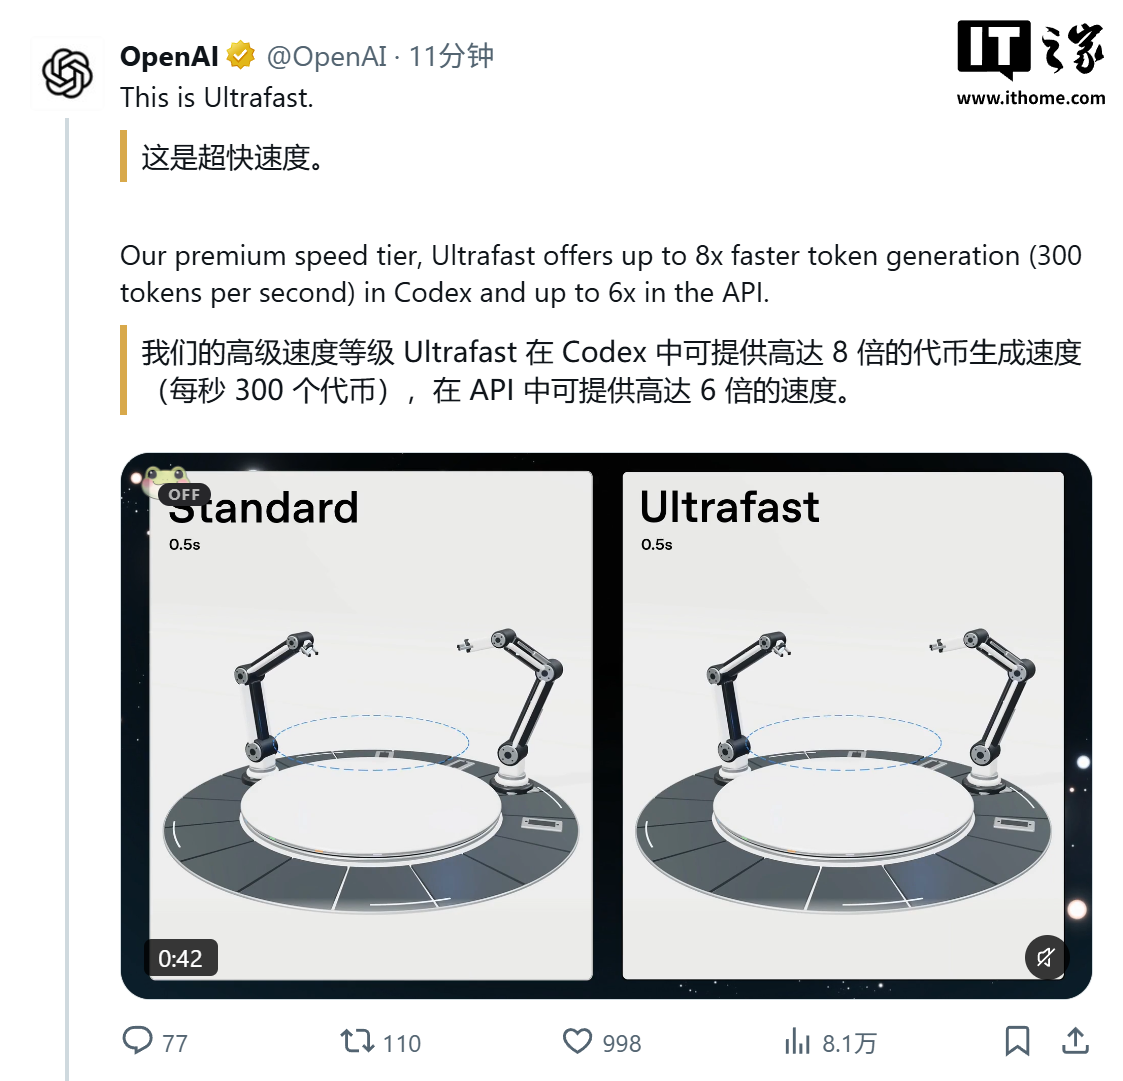
According to the introduction, the value of Ultrafast lies in its ability to balance both “more powerful models” and “real-time response.” In the past, to achieve near-real-time speed, it was often necessary to switch to smaller or more specialized models; whereas Ultrafast attempts to increase the “useful workload per second” while maintaining the capabilities of GPT-5.6 and Sol, making it more suitable for scenarios such as event response, real-time customer service, generation of transaction/market updates, and interactive coding.