

















Enterprise data analysis is crossing a very practical threshold: business personnel no longer need to learn SQL first, nor do they have to switch back and forth between a dozen dashboards. By simply asking questions in natural language, the system can find the data, verify the criteria, trace the causes of changes, and then present the conclusions in interactive charts. OpenAI released on September 10th its Data agent, which aims to incorporate this process into ChatGPT Work. It connects not only to files but also includes Redshift, BigQuery, Databricks, Snowflake, ClickHouse, MongoDB, and Datadog among other enterprise data sources, and is capable of reading documents from Google Drive and SharePoint.
This is not about adding a "draw picture" button to the chat box. Traditional business intelligence tools are used to present already organized indicators, while Data Proxy attempts to participate in the entire process before and after a query: understanding the company's definitions of revenue, retention rates, and customer segmentation, finding the corresponding tables and fields, generating queries, checking for anomalies, and then handing over the results to business personnel for further investigation. OpenAI states that almost all product teams within the company, as well as more than two-thirds of the marketing and sales teams, are already using Data Proxy. This figure indicates the level of adoption of the product within a technology company, but it does not directly prove that the same results can be achieved in every enterprise.
Shifting from "finding reports" to "investigating issues", the value lies in the data foundation.
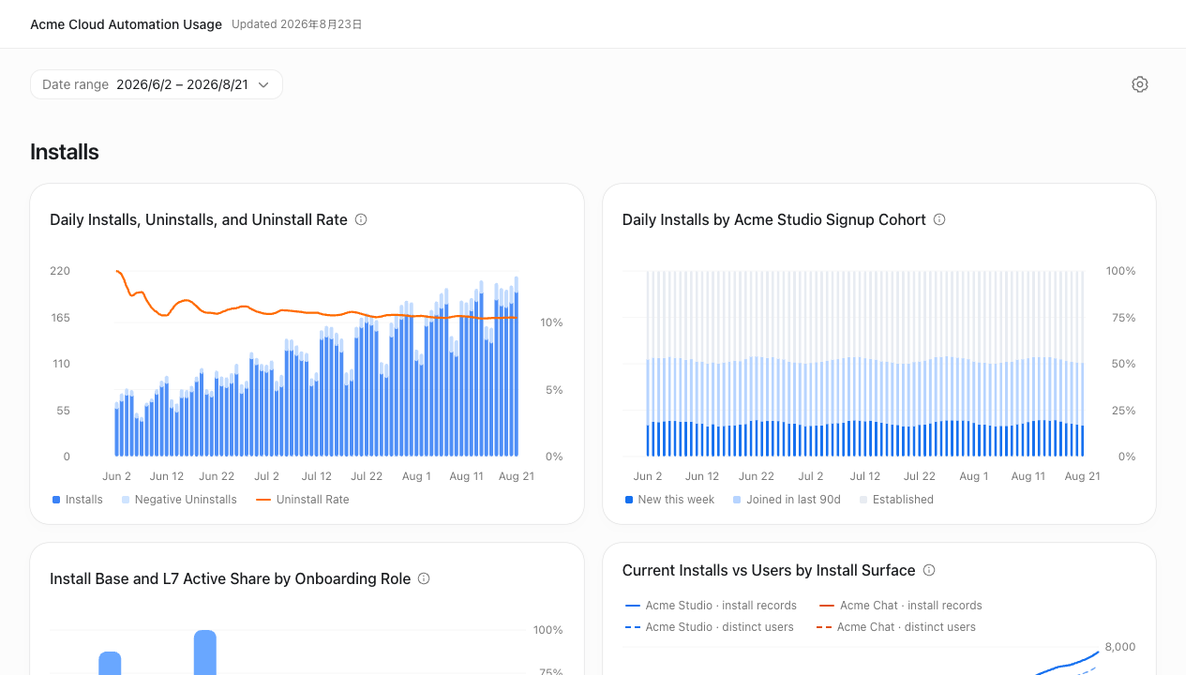
Many companies are not short of reports; what they lack is the time to get to the bottom of issues. When sales managers notice a decline in renewal rates in a certain region, they often have to first confirm the definitions with analysts, then wait for the data team to write queries, and subsequently, due to variations in samples, refunds, or exchange rates, they have to recalculate the figures. Data agent We hope to streamline this back-and-forth process into a single, continuous investigation. Users can ask for explanations as to why a certain metric has changed, or they can continue to narrow down the scope by specifying industry, region, product version, or customer size, ultimately resulting in an interactive dashboard.
What truly determines whether the answer is credible is not whether the model can generate SQL, but whether it can understand the enterprise's own “semantic layer.” The support methods listed in OpenAI include Databricks Genie Ontology, dbt projects, GitHub materials, Snowflake Horizon, as well as the existing dashboards in Omni, Oracle BI, Power BI, Sigma, Tableau, and ThoughtSpot. In other words, the system will try to use the business definitions that have already been recognized by the organization, rather than guessing the meanings from field names each time. For the same “active user,” the product, finance, and marketing departments may have three different sets of algorithms; if the semantic layer is not unified in advance, the agents will only produce conflicting figures more quickly.
Natural language alone will not eliminate data quality issues. Duplicate orders, time zone mismatches, delayed data entry, and contamination of experimental groups can all lead to incorrect conclusions from a grammatically correct query. Data proxies can compare sources, display the reasoning process, and cite specific data, but companies still need to assign responsible persons for key indicators, set refresh times, and implement quality alerts. The most suitable tasks for data proxies are exploratory work and preliminary troubleshooting; however, high-risk decisions involving financial reports, performance bonuses, and compliance submissions must still be reviewed by data or finance personnel.
This time, the product also emphasizes permission inheritance. Administrators decide which sources and roles can be connected to, and queries continue to follow the user's table-level, row-level, and column-level permissions within the respective systems. This is more important than "responding like an analyst": a company-wide chat entry point can easily expose salary information, customer lists, or unpublicized business data to unauthorized individuals if it bypasses the existing permission settings. Even if the permission mechanism is correct, administrators still need to check whether exporting, caching, sharing conversations, and dashboard links may lead to secondary dissemination of such information.
After the analysis speed is improved, enterprises need to redesign their review processes and responsibility chains.
The most common misunderstanding associated with data proxies is regarding the ability to generate “quoted answers” as an indication that the answers have been audited. Quotes can only indicate where the data comes from; they cannot automatically determine whether the definition of the metrics is applicable to the current question. For example, when a marketing team asks about the cost of acquiring new customers, the system may accurately provide information on advertising expenditures and the number of accounts opened. However, if it overlooks factors such as agency commissions or the time lag between trial periods and paid subscriptions, the results are not suitable for direct presentation in budget meetings. Enterprises need to categorize types of questions: for everyday exploratory purposes, immediate use is acceptable; for management decisions, confirmation from the metric owners is required; and for external disclosures, formal control processes must be followed.
A practical process should at least include user questions, the data sources used, the queries executed, the key filtering conditions, the generation time, and the final modification records. This way, when numbers change, the team can determine whether there has truly been a change in business operations, whether the source tables have been updated, or whether the proxy is using different criteria. For automatically generated dashboards, it is also important to specify the refresh frequency and the data cutoff time to prevent managers from mistaking last week's data for real-time information.
The cost structure will also change. In the past, a large amount of time was spent by the analysis team on repetitive data retrieval and formatting. Proxies may free up some of this time, but that does not mean the data team will disappear. On the contrary, they will focus more on maintaining the semantic layer, permissions, quality testing, and common indicators. As business personnel can pose more questions, the volume of queries faced by the organization may increase significantly, and the costs associated with data warehouse calculations, access auditing, and model usage will need to be re-evaluated.
The early users listed in OpenAI include companies such as NTT DATA, Thermo Fisher Scientific, and ServiceTitan, but these cases can only represent specific environments. Whether the system can be effective within a company depends on whether the data is accessible, whether there is someone responsible for the metrics, whether the permissions are detailed enough, and whether employees know when to doubt the answers. Plugin and data source integration also require administrator configuration; not all ChatGPT users automatically obtain all capabilities.
The real change brought about by Data and agent is the expansion of data analysis capabilities beyond professional tools to more positions. It provides the opportunity for issues to be addressed more quickly with initial solutions, and it also exposes the discrepancies in approaches that were previously hidden within analysts' experience. If a company only purchases tools without organizing data definitions, what it may end up with is a machine that rapidly generates disputes; however, if semantics, permissions, and review processes are established first, then these tools can transform analysts from data collectors into investigators, allowing business personnel to make decisions based on the same set of credible facts.