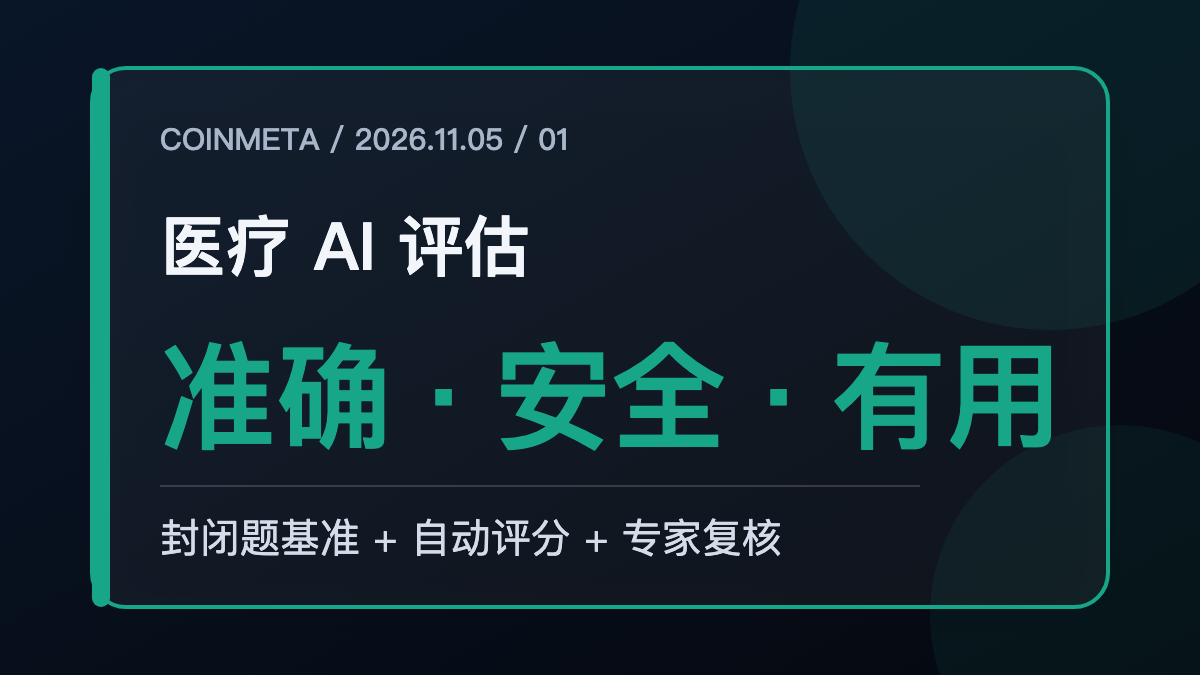
A medical artificial intelligence system that answers 90% of the questions correctly – is that considered safe? However, if the remaining 10% of cases involve emergency triage, drug contraindications, or high-risk populations, the seemingly good average score may actually conceal the real dangers. On November 4th, Google announced an end-to-end evaluation framework for health scenarios that measures accuracy, safety, and usefulness separately. It also integrates closed-ended question benchmarks, automatic scorers, and expert manual reviews into the same evaluation process. The significance of this initiative lies not in the addition of another ranking system, but in its advancement of medical AI from simply being able to answer questions to being trustworthy in specific contexts.
The three scores cannot replace each other.
In general model evaluations, the correct answer is often regarded as the core goal, but health issues are not simply about "right" or "wrong." A statement that is medically correct may lack usefulness if it does not provide guidance on when to seek medical attention; a piece of advice that ignores factors such as age, pregnancy, chronic diseases, or medications being taken may still be unsafe, even if it is well-worded; and providing only conservative warnings, while reducing risk, may prevent users from obtaining actionable information. By placing accuracy, safety, and usefulness on an equal footing, Google acknowledges the tension that exists among these three aspects, and any single score that prioritizes one over the others will miss part of the clinical significance.
The framework covers both common issues and high-risk scenarios. Common issues are used to test the stability of the model, while high-risk scenarios determine whether the system is qualified to enter real workflows. The two cannot be treated with the same set of priorities: no matter how well a response to a cold is given, it cannot offset a mistake in chest pain triage. For product teams, this means that the test set should not only focus on quantity but also need to be stratified by level of risk, and separate blocking rules should be reserved for the few but severe failures.
Why do we still need experts for automatic grading?
Automatic scorers are suitable for quickly scanning a large number of responses to identify obvious factual errors, omissions, or inconsistencies; closed-ended question benchmarks are suitable for comparing versions to determine whether there has been a regression in model capabilities after upgrades. However, medical advice often relies on context, and many answers cannot be judged in just one sentence. For example, whether it is reasonable to "observe first" depends on the duration and severity of symptoms, as well as accompanying signs; "consult a doctor" may also be a mere formulaic response, and does not prove that the system truly understands the risks.
Expert manual review is not just for decoration; rather, it brings clinical judgment back into the evaluation process. Experts can check whether the model addresses key conditions, whether uncertainties are clearly explained, and whether necessary upgrades are made when needed. More importantly, experts can explain why an answer is not qualified, helping the team turn failures into reproducible test cases. Only by forming a cycle of "automatic scanning to identify issues—experts defining risks—new version regression verification" can evaluation truly impact the product, rather than remaining merely in the materials for the launch event.
What the evaluation framework changes is the way of going live.
If a set of healthy AI systems is only tested once before going live, it can quickly be dragged beyond its original safety boundaries by new model versions, prompts, knowledge bases, and user behaviors. An end-to-end framework is more suitable for being used as a continuous security mechanism: every time there is a change to the model or system, common and high-risk scenarios are retested; if any critical risks worsen, the release is paused. Additionally, it is necessary to retain the anonymized records of failures and manual upgrade logs online to observe real issues that were not covered in laboratory tests.
This approach will also change the communication between procurement and supervision. Hospitals or health platforms should not only ask about the “model score,” but should also request to see the coverage of scenarios, the distribution of failures, the methods of manual review, and changes in versions. Developers need to explain which issues can be handled, which issues must be referred to professionals, and what actions the system will take when it encounters insufficient information. Credibility comes from transparency at the boundaries, not from a seemingly high percentage.
More realistic insights for the industry
In the competition of medical AI, it is very likely that not just the largest models will win. Whether a stable evaluation process can be established, whether high-risk failures can be prevented before launch, and whether clinical feedback can be continuously incorporated, all of these will become factors that differentiate products. Small models, if they have clear boundaries in specific scenarios, may be more valuable than large models that are willing to answer anything.
Google makes this approach public, also reminding the market not to confuse "model capabilities" with "product security." The former describes what a model may be able to do, while the latter depends on data, interaction, monitoring, human intervention, and responsibility design. A truly mature medical AI does not always provide answers; instead, it provides reliable answers when they are needed, acknowledges uncertainty when information is insufficient, and hands over decision-making to professionals when risks increase. That is the threshold from demonstration to real-world medicine.